MAI Code 2 and Code 2 Flash: Everyday coding at scalable prices
 Source
·Ignite ·Models
More of what makes a company distinctive will live inside the AI models it runs. Businesses increasingly want to control those models: who can access them, how they’re adapted, what they cost to operate, and when they’re upgraded.
That’s why we’re introducing MAI Licensed Weights, giving organizations the ability to deploy and customize Microsoft AI models in their own Azure environments.
MAI Licensed Weights brings Microsoft’s frontier AI models into your own Azure environment, where you can adapt them to your business and safely integrate your proprietary knowledge and expertise. Your data and adaptations remain yours, with Microsoft only using them to train its models with your express agreement.
As these models become embedded in your most important products and workflows, you retain control over how they’re deployed, who can access them, and when they’re upgraded. That means you can innovate at your own pace, without compromising the continuity your business depends on.
The best model for a business isn’t necessarily the largest or most powerful general-purpose model. It’s the one that delivers the best performance on the tasks that matter, at a cost that makes deploying AI at scale viable.
By adapting MAI models to their proprietary knowledge and workflows, customers are achieving frontier-level or better performance on specialized tasks, at a fraction of the cost.
AT&T used MAI models to analyze 5G networks. For standard tasks, MAI outperformed GPT-6.1 Sol at just 1/50th of the cost.1 For more complex tasks, it achieved frontier-level performance at a significantly lower cost.
Other customers have demonstrated similar results:
These results show what becomes possible when companies combine Microsoft’s frontier AI research with their own expertise: better performance on the tasks that matter, at dramatically lower costs. As more of that expertise becomes embedded in AI models, the ability to control and evolve them becomes increasingly valuable.
MAI Licensed Weights is coming soon through our Frontier Company engagements. To learn more, contact your Microsoft account team.
About these results
Results reflect customer-specific evaluations of models adapted for particular tasks. Performance and cost advantages vary by workload, model configuration, and evaluation methodology.
·Ignite ·Models
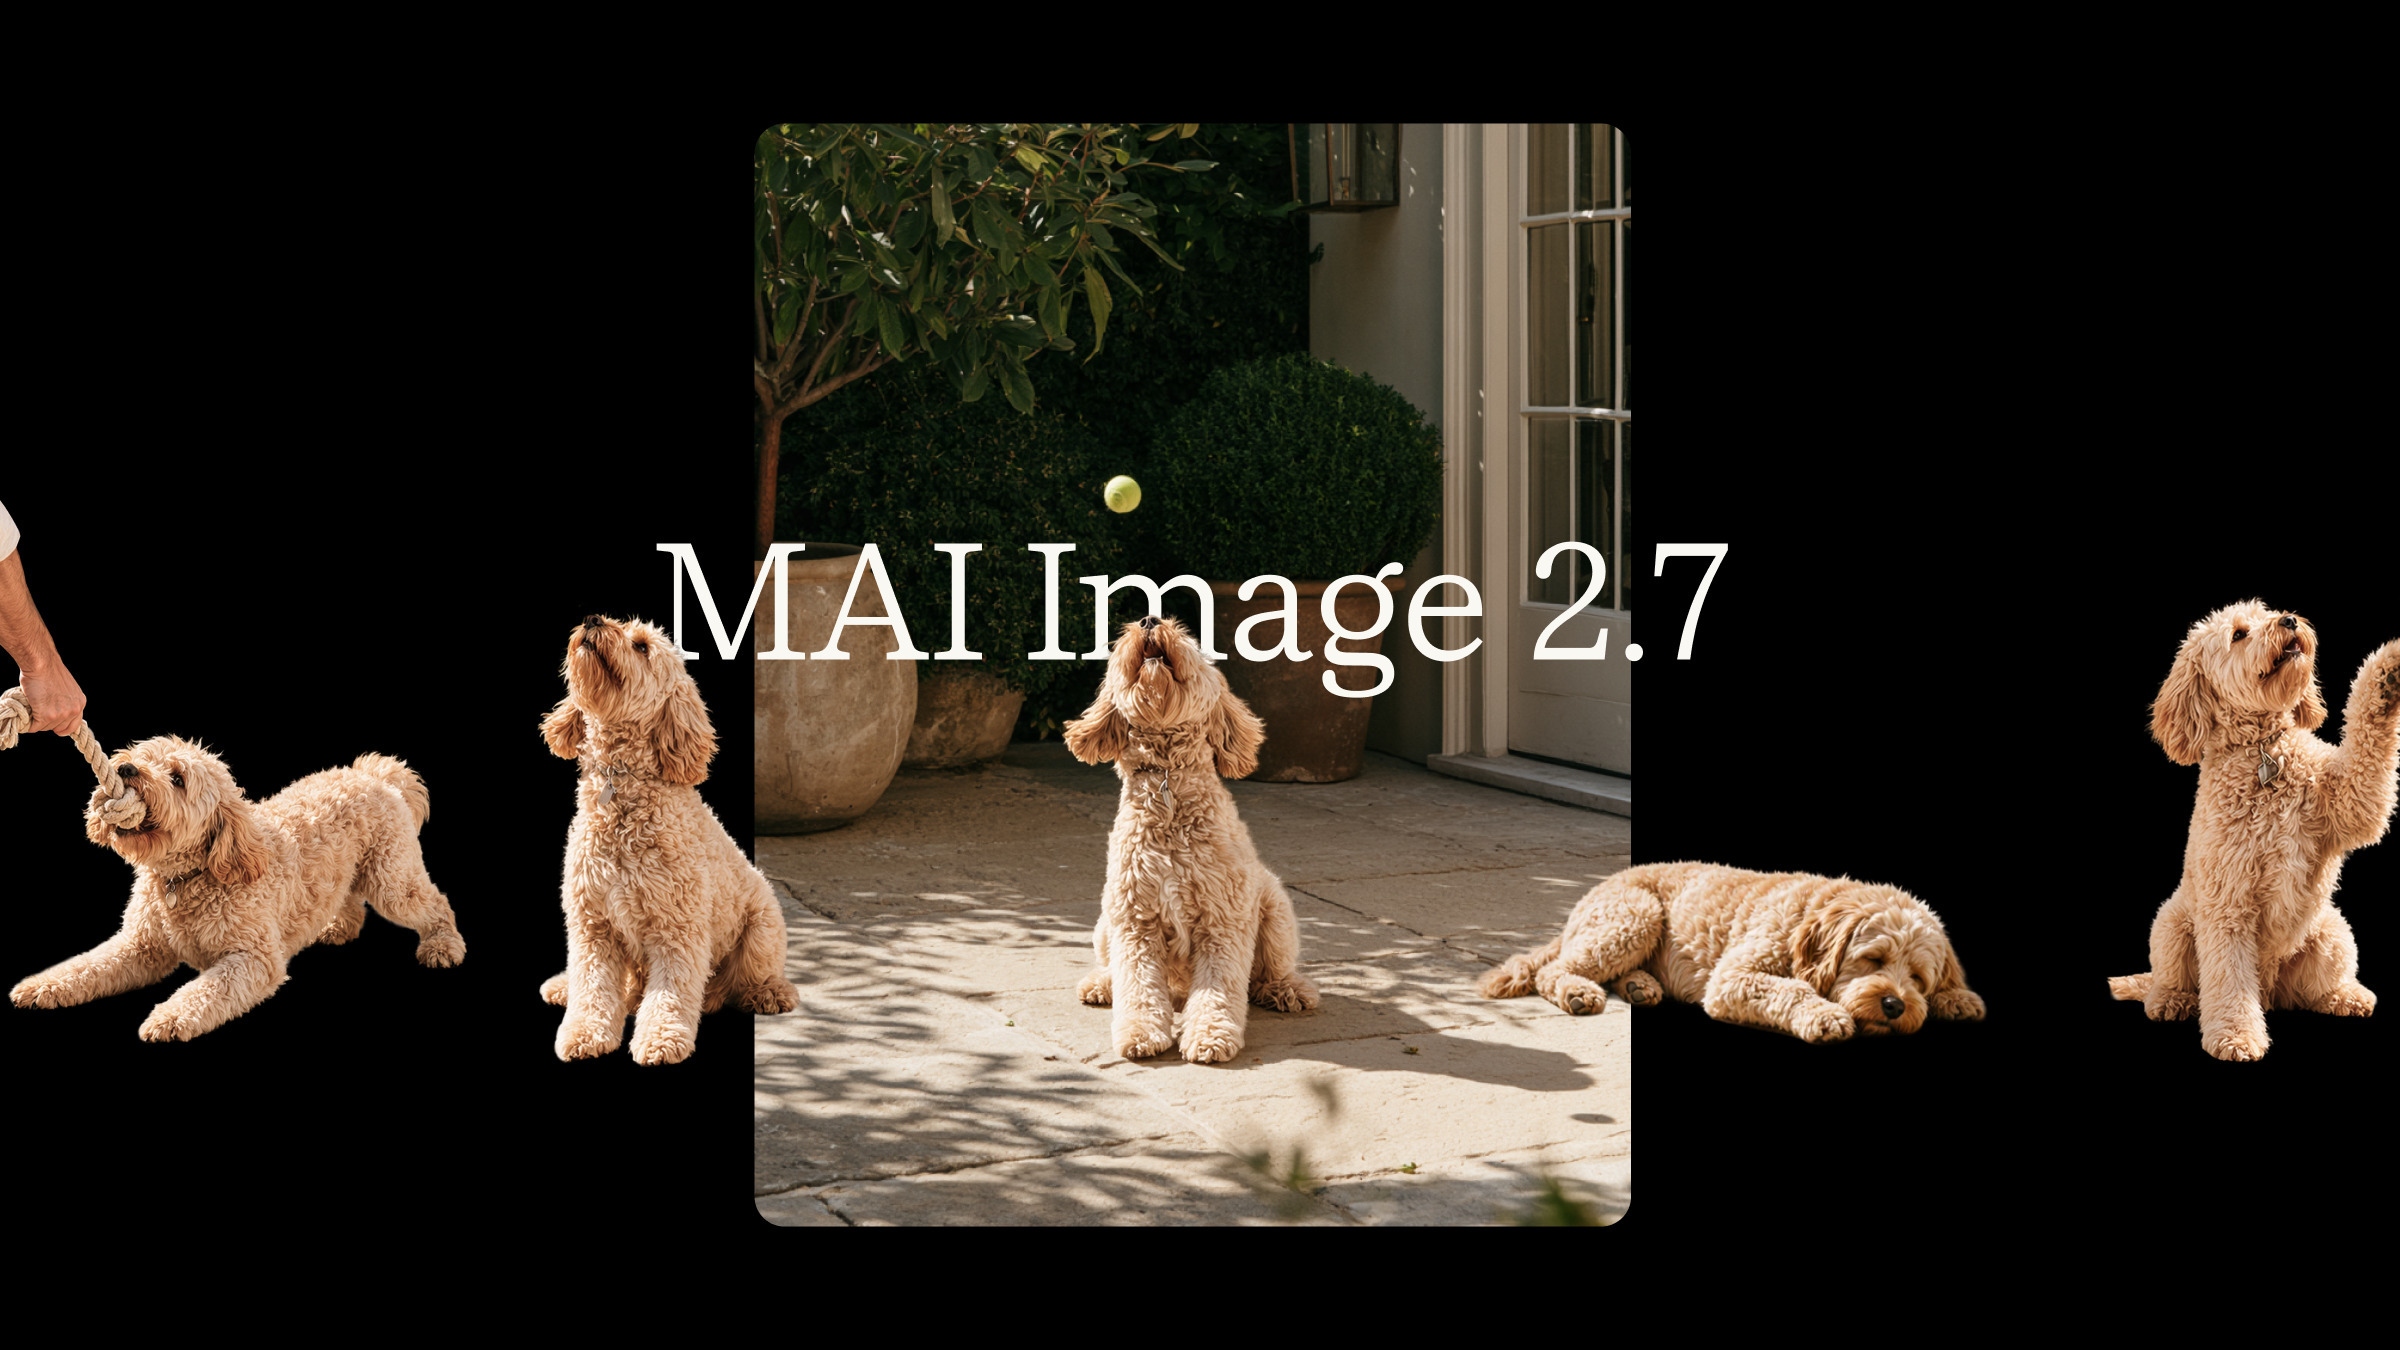
Today we’re introducing MAI Image 2.7 and MAI Image 2.7 Flash, delivering frontier image generation and editing at a fraction of the cost of the leading competitors. We’re also launching Canvas, a new interactive workspace powered by our Flash model to create, edit, and refine images.
MAI Image 2.7 takes the #1 spot on Artificial Analysis image editing, outperforming GPT Image 2.6 Sunburst (max) at just one-fifth of the cost. On Arena, MAI is a top-two lab in both image generation and editing, outperforming GPT Image 2.6 Flare 1. Flash delivers the speed and efficiency needed for production workloads, with both models on the quality-cost Pareto frontier for image generation and editing.
Available in public preview on Microsoft Foundry, MAI Image 2.7 costs ~$35 per 1,000 images while Flash costs ~$10 per 1,000 images.2
Change an object’s color, material, or position without disrupting the rest of an image. MAI Image 2.7 preserves visual consistency across successive edits, allowing creators to refine results and explore variations without starting over.
Both models support transparent backgrounds for ready-to-use product images, logos, icons, and illustrations without manual cutouts or cleanup.
Canvas is a new interactive experience in MAI Labs, powered by MAI Image 2.7 Flash. Start with a prompt or sketch, turn rough ideas into polished diagrams, then select any part of an image to replace, move, or restyle, all in one space.
MAI Image is now the default model family powering Bing Image Creator, with usage growing at a compounded weekly growth rate of ~15% since June.3
Creative platforms and businesses including Adobe, Figma Weave, Minute (Sports Illustrated), Wirestock, and Manus are also working with MAI Image.
Try MAI Image 2.7 and MAI Image 2.7 Flash in MAI Labs, including Canvas.
Both models are available in public preview through Microsoft Foundry and partners including fal, Genspark, OpenRouter, and Vercel.
“Adobe Firefly, our AI creative studio, gives creators a choice of leading models and tools as they move from idea to finished content, and MAI Image 2.7 within that will give creators another option to tailor their images with strong prompt adherence.

“At Minute, we're constantly exploring new technologies that can strengthen our creative capabilities across brands like Sports Illustrated. In our early testing of Microsoft's MAI Image models, we were particularly impressed by the visual quality, composition and precision of targeted design edits. We see exciting potential for these models to help our teams develop creative concepts, explore ideas and refine designs, while maintaining the creative control and standards our brands are known for.
“We’re excited to bring MAI Image 2.7 to Figma Weave. We built Weave to give teams more space for creative exploration and more control to bring their vision to life. Adding Microsoft’s latest image model unlocks new ways for our community to push their creativity further with Weave.
“MAI Image 2.7 reads a scene the way a photographer does. It's excellent at understanding scenes, preserving details, and making realistic changes to objects, lighting, angles, and backgrounds. Across a diverse set of real-world tasks evaluated by the team at Wirestock, a leading visual training data provider, MAI Image 2.7 shows a genuine leap forward for AI image editing.
“In our testing, MAI Image 2.7 delivered compelling stylized images, carried key visual elements over faithfully from reference images, and made localized edits that were accurate, consistent and quick.
About these results
Results reflect specific model configurations and evaluations. Performance, speed, and cost comparisons vary by workload and methodology.
·Ignite ·Models
MAI Realtime 1, our first speech-to-speech model, is built for naturally flowing conversations in real-world enterprise applications starting at $0.01 per audio minute.1
Our model outperforms GPT Realtime 2.1 on quality, speed, and price across public benchmarks and Microsoft product evaluations. It sits on the performance-price Pareto frontier for both Big Bench Audio speech reasoning and Tau-Voice agentic task completion benchmarks.2
Building a voice agent people actually want to talk to takes more than just a good voice. It takes the right mix of conversation, intelligence, and action working simultaneously. MAI Realtime 1 brings that together through the following capabilities:
MAI Realtime 1 is also compatible with the OpenAI Realtime API, making it straightforward for developers to test the model and migrate existing voice applications.
Companies including Agoda and Reservations.ai are already putting MAI Realtime 1 to the test.
We’re also bringing MAI Realtime 1 to Dynamics 365 Contact Center for customer service applications, and to Dragon Copilot, to support AI-simulated patient conversations that help nurses practice clinical interactions.
About these results
Results reflect specific evaluation configurations and workloads. Performance, latency, and cost comparisons vary by application and methodology.
·Announcements ·Ignite
At MAI, our mission is to build you the very best models in the world and keep every developer and every enterprise at the frontier of capability.
But as token spend skyrockets, we know that you also want models at a price point that lets you run agents 24/7 doing real engineering work.
That’s why today we’re releasing a family of seven new world class models at a truly exceptional price-performance.
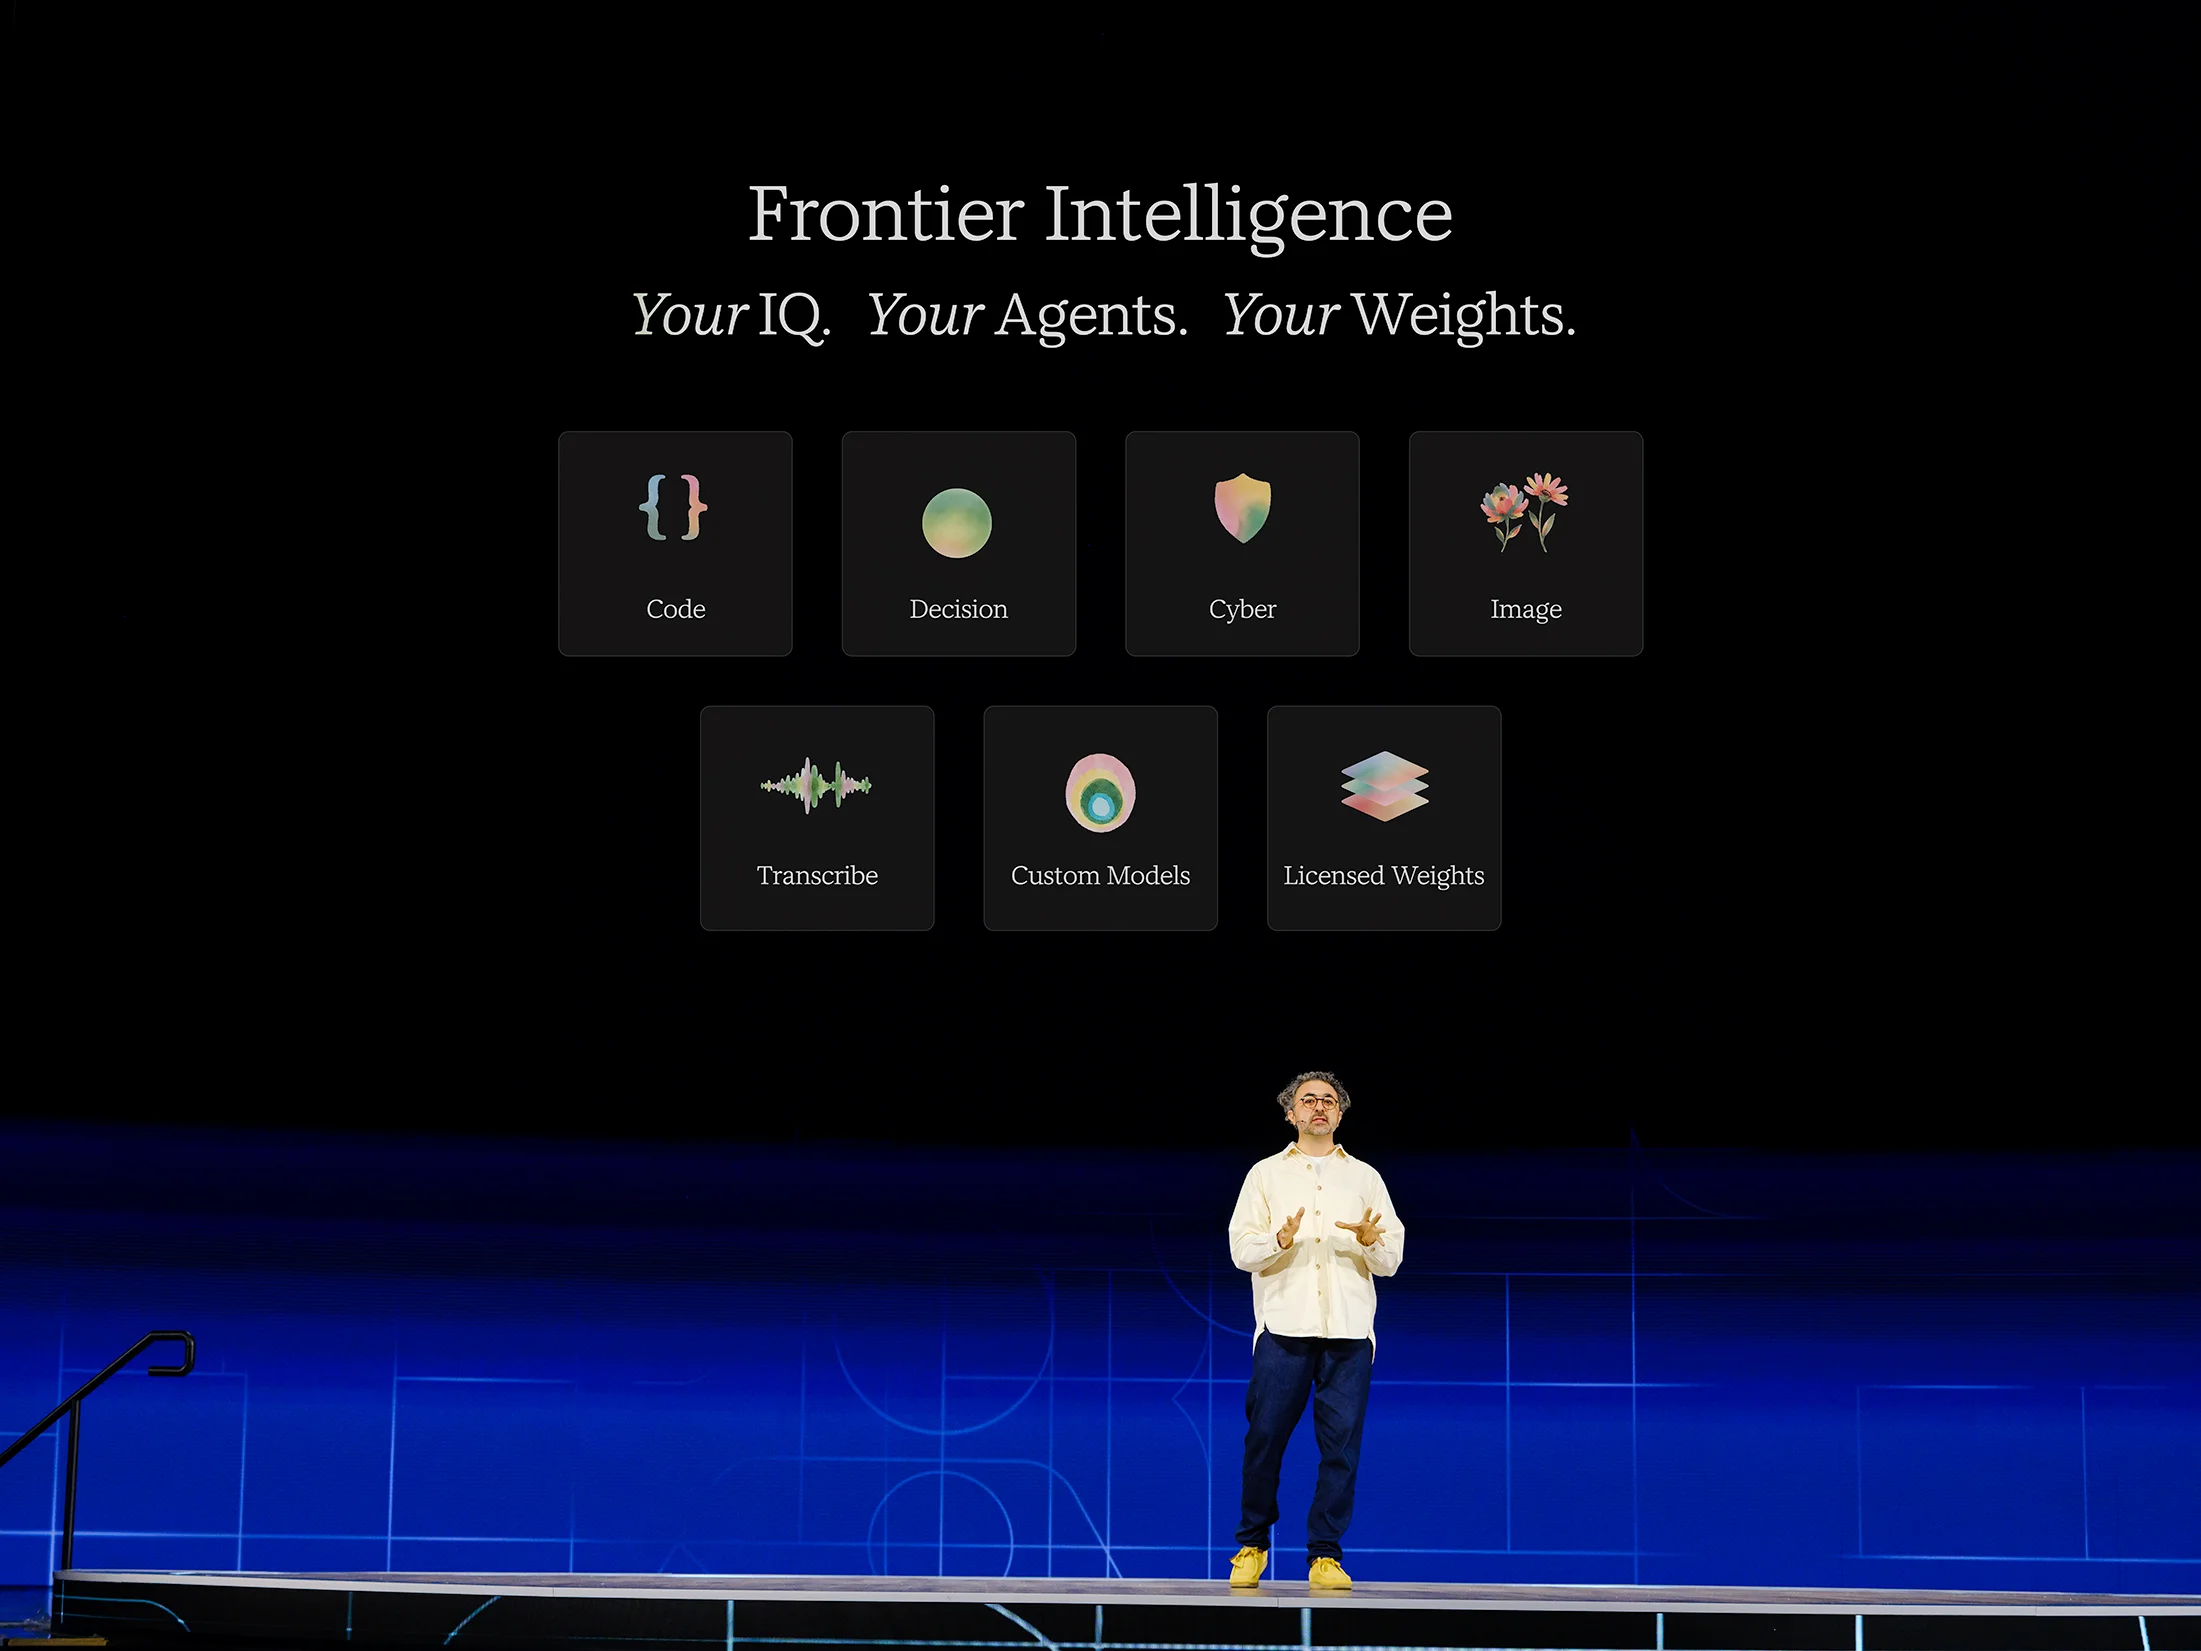
Here’s the lineup:
Security, alignment and containment are the most important priorities for agent development in 2027 and beyond. That’s our top priority. We need to run monitoring and control agents defending and patching live production systems 24/7. That’s why MAI Cyber 2 Flash was designed to deliver frontier intelligence at a fraction of the cost.
Built with Microsoft’s decades of proprietary data and world-class security expertise, our models help defenders stay safe in this new era where attackers have cheap and abundant offensive tools.
MAI Cyber 2 Flash builds on earlier MAI Cyber models that defenders already rely on. MAI Cyber accounts for almost 40% of scans in MDASH, and 90% of scans that started with MAI continued to use it. Our latest model is now priced 86% lower on output tokens than MAI Cyber 1.1 Flash, giving existing MDASH customers a stronger model at a lower price.
MAI Code 2 is built for the best price-performance for everyday enterprise coding tasks. Averaged over four widely used benchmarks that target the everyday enterprise coding tasks we see in GitHub Copilot (DeepSWE 1.1, Terminal Bench 2.1, SWE-Atlas and FrontierCode v1.1), MAI Code 2 gives you 98% of the performance of GPT-6.1 Sol at 40% of the price, and 96% of Claude Opus 5.5’s performance at just 5% of the price.
We’ve built these models to prioritize the coding work our customers do every day. They’re explicitly not yet tuned for harder problems, like fundamental science research and very long horizon agentic work.
MAI Code 2 also been tuned to generate great dashboards and visualizations. In a blind, side-by-side evaluation of frontend work, developers preferred MAI Code 2 over GPT-6 Sol 64% of the time. Try MAI Code 2 in GitHub Copilot today. Read more here.
MAI Code 2 Flash is designed for high-volume, everyday tasks like code explanations, targeted edits, routine fixes, and rapid iterations, while bringing quality at a much lower cost. It performs comparably to GPT-6 Luna and Claude Haiku 5.5 at 65% and 20% of the price, respectively, across three coding benchmarks measuring day-to-day, high-volume routine coding tasks (DeepSWE 1.1, Terminal Bench 2.1 and SWE-Atlas). It’s available in GitHub Copilot and in a limited-access preview in Microsoft Foundry.
MAI Image 2.7 is the best image editing model in the world, taking the #1 spot on Artificial Analysis, outperforming GPT Image 2.6 Sunburst (max) at just one-fifth of the price. At text-to-image generation, our model is ranked #4, making us the second-best lab. And MAI Image 2.7 Flash brings world class image generation for high-volume scenarios at ~$10 per 1,000 images. Both are available in Microsoft Foundry here.
MAI Realtime 1 is our first live speech-to-speech model, designed for natural, low-latency conversations. In our evaluations, it outperformed GPT-Realtime 2.1 across external and Dynamics 365 benchmarks. It’s priced for enterprise-scale use, starting at a budget-saving price of $0.01 per audio minute. You can try it out in MAI Labs and register your interest here.
Dragon Copilot Transcribe, built on MAI Transcribe 2, is now live in Dragon Copilot, powering 100% of doctor–patient conversation transcriptions. It covers 10 million encounters a month, halves error rates in multilingual workflows, and is in the hands of a third of US physicians.
Decision 1.1 provides model routing integrated right into your applications so that the bigger, pricier models are only used when you really need them. On the Artificial Analysis Decision Index Microsoft is ahead of Jev, Google and OpenAI, while being faster and cheaper. Used by 4,000 customers, it’s 50x faster and 79x cheaper than GPT-6.1 Sol.
We’ve heard again and again from leaders that no one wants to pour their IQ into someone else’s model.
And if you build on open weights, can you really trust where they came from, or how they’ll behave when you use one as the foundation for your most valuable IP and data?
We heard you. We started with Custom Models. AT&T developed an MAI custom model for 5G network operation analytics and it outperformed GPT-6.1 Sol at 1/50th of the cost. On complex scenarios, they found that Code 2 delivered frontier-level performance at a significantly lower price than alternatives.
Today, we’re taking a big step forward with MAI Licensed Weights: models under your control.
Take a frontier MAI model, customize it using your proprietary data if you want to. Then run it securely in your own Azure environment.
You control who can access it. Your data and adaptations stay yours. And we’ll work with you through Frontier Company to deliver the custom model and embed it in your own products and agents.
So that’s MAI, a family of world class models with exceptional price performance: the world’s best image editing model; the world’s best transcription model; frontier cyber defense at 2% of the cost; and world class everyday coding models at a price you can scale.
And crucially all of it with Your IQ. Your agents. Your weights. All under your control.
This is Frontier Intelligence you can trust, from the company you can trust.
·Ignite ·Models
Security teams need AI to find vulnerabilities, recommend fixes, and investigate threats around the clock.
Doing that at scale takes serious computing power, and the cost can quickly add up.
Built on Microsoft’s decades of proprietary security data and expertise, MAI Cyber 2 Flash is our latest specialist security model. It delivers leading performance on real-world security tasks at a fraction of the cost of larger models. And we’re bringing that capability directly into Microsoft’s security products.
On CyberGym‑E2E1, a benchmark measuring real-world vulnerability discovery, MAI Cyber 2 Flash (92.3%) beats GPT-6 Astra (91.5%)5 at less than 2% of the cost per task.3 It also outperforms GPT-5.6 Cyber6 on CyberGym‑E2E and WebExploitBench at the same reasoning budget.2
With a one-million-token context window, four times larger than MAI Cyber 1.1 Flash, it can analyze more of a codebase during complex, multi-step investigations. Early evaluations through Microsoft Perception show performance comparable to leading models on investigation agent and security-detection authoring tasks.
We’re already seeing what specialist models can deliver in customer environments: Insight Enterprises found MAI Cyber models to be 20% more token-efficient than the GPT models it tested in its evaluations.4
These results point to a bigger opportunity: bringing advanced security capabilities to more workloads, without the cost of running larger models at every step.
MAI Cyber 2 Flash is coming exclusively to Microsoft security products, including Codename MDASH, where it will automatically replace the existing model in the MAI profile for eligible customers starting mid-December.
About these results
Results reflect evaluations on specific security tasks and configurations. Performance and cost comparisons vary by workload, model configuration, reasoning effort, and evaluation methodology.
·Ignite ·Models
MAI Code 2 and MAI Code 2 Flash: two new coding models built for everyday enterprise coding tasks, delivering leading performance at a fraction of the cost of competing models.
MAI Code 2 is at the frontier of price-performance for common enterprise coding tasks and excels in taking code to production, deep debugging, multi-file implementation, repo-wide reasoning, and UI. It does all of this while also delivering changes code maintainers would merge, at a fraction of frontier cost.
Meanwhile, MAI Code 2 Flash is designed for high-volume work such as code explanations, targeted edits, routine fixes, and rapid iterations, while bringing quality at a much lower cost.
To deliver the best price-performance, we’ve built these models to prioritize the coding work our customers do every day. They’re explicitly not yet tuned for harder problems, like fundamental science research and very long-horizon agentic work.
Averaged over four widely used benchmarks that target the everyday enterprise coding tasks we see in GitHub Copilot (DeepSWE 1.1, Terminal Bench 2.1, SWE-Atlas and FrontierCode v1.1), MAI Code 2 gives you 98% of the performance of GPT-6.1 Sol at 40% of the cost, and 96% of Claude Opus 5.5’s performance at just 5% of the cost.1
MAI Code 2 is also tuned for producing great dashboards and visualizations, and excels at visual coding. In blind frontend app evaluations, developers preferred its results over GPT-6 Sol 64% of the time.2
In addition, MAI Code 2 Flash offers comparable performance to GPT-6 Luna and Claude Haiku 5.5 at 65% and 20% of the cost, across three coding benchmarks measuring day-to-day, high-volume routine coding tasks.3
MAI Code 2 is also becoming the workhorse behind Microsoft products. From Code 2 Flash, we further optimized a single model, MAI Work Flash, to serve multiple Microsoft products across Microsoft 365 and FabricIQ.
Excel: Our model is on par for accuracy and token efficiency with GPT-6 Luna across key internal Excel customer-scenario benchmarks.
PowerPoint: On key production benchmark scenarios that measure frequent PowerPoint tasks, our model performs on par with GPT-6 Luna in both quality and token efficiency.
Word: Our model performs similarly to GPT-6.1 Sol (while being significantly smaller) on 5 key internal benchmarks using ~42% fewer input tokens per call than GPT-6.1 Sol in production.
Teams: Our model beats GPT-6 Luna at tracking decisions, filling knowledge gaps, and adapting to custom instructions using up to 28% fewer tokens on instruction following and tool calling.
FabricIQ: In offline evaluation runs, our MAI model outperforms GPT-5.6 Sol, GPT-6 Astra, and Claude Opus 5.5 at DAX query generation, the core capability behind “Chat With Your Data” for Power BI semantic models.
Get started
MAI Code 2 and Code 2 Flash are available in GitHub Copilot, and Code 2 Flash is in limited-access preview in Microsoft Foundry. Soon, we’ll be releasing them on OpenRouter, Vercel, Hermes, OpenCode, and Kilo.
Learn more about customizing MAI Code 2 on our Custom Models page.
About these results
Results reflect evaluations on specific coding tasks and configurations. Performance and cost comparisons vary by workload, model configuration, reasoning effort, and pricing assumptions.
·Ignite
Our mission at MAI is to build you the very best models in the world, and to keep every developer and organization right at the absolute frontier of capability.
But what I hear time and again from every CIO and CFO is that right now token spend is going through the roof. And at frontier prices, the math just isn’t sustainable.
So our commitment is to give you the very best price-performance out there so you can really scale your agents.
And we know you want models that feel truly yours, where you control the weights.
We don’t just hill-climb on frontier quality alone. We co-optimize quality and price together.
And we keep doing it, over and over. We ship, we learn, we improve, we repeat.
Take coding, for example.
Averaged over four widely used benchmarks that target the everyday enterprise coding tasks we see in GitHub Copilot, MAI Code 2 gives you 98% of the performance of GPT 6.1 Sol at just 40% of the cost, and against Opus 5.5 it’s an incredible 5% of that cost.
Same for Code 2 Flash. It matches 6 Luna and Haiku 5.5 on these everyday tasks, at just 65% and 20% of the price, respectively.
But agents are increasingly needed to make decisions, especially where speed and cost are critical.
So Decision 1.1 provides model routing integrated right into your applications. And on the Artificial Analysis Decision Index it beats Jev, Google and OpenAI.
Now, it’s important to say, we’ve built these models to prioritize the coding work our customers do every day. So they’re explicitly not yet tuned for the harder problems, like fundamental science research and very long horizon agentic work.
And we won’t chase those more niche capabilities at your expense. Because after all, when the same model is built to also push the frontier of science, you pay for that capability on every task, even for a routine bug fix.
So our commitment is to keep pushing the price-performance frontier on what matters most to you.
And a great example is AT&T’s custom version of Code 2 Flash. It outperforms 6.1 Sol on standard 5G network analysis, while being a whopping 50x cheaper.
Now it’s the same story in cybersecurity. The last few months have been a warning shot and a wake-up call for all of us.
We’re now facing a new reality where attacks and exploits are cheaper and easier and more ubiquitous than ever before.
That means agent security, alignment and containment are going to be the most important things to get right in 2027 and beyond.
MAI Cyber 2 Flash is our response. It’s ahead of GPT 6 Astra on CyberGym-E2E at less than 2% of the cost per task. Truly remarkable.
You know, that’s the power of Microsoft’s decades of proprietary data and world-class security expertise enabling us to bring you a model that not only detects the vulnerabilities, but recommends the right fixes at an incredible price.
We’re also moving just as fast in multimodal. We’re now the number two lab on image generation and MAI Image 2.7 just this morning is the world’s number one image editing model at a fifth of the cost of the competition.
Customers like Adobe, Sports Illustrated and Manus say it gives them professional quality with super precise and responsive edits.
And our transcription model is the fastest and most accurate in the world. And of course, medicine is probably the most important, most complex, and high-stakes of all AI applications.
MAI Transcribe 2 has now been deployed to 10 million patient Dragon Copilot encounters a month, while halving the error rate.
We are committed to giving you frontier performance at a price point you can run 24/7.
So Judson said it at the top: Your core assets in this new platform shift are your IP and your workflows, the years of commercial data you’ve assembled, essentially everything that makes your company what it is. Your IQ.
I’ve heard again and again from leaders, no one wants to pour their IQ into someone else’s model.
And if you build on open weights, can you really trust where they came from, or how they’ll behave when you use one as the foundation for your most valuable IP and data?
And so we heard you. We started with Custom Models, as we just saw with Alaska and AT&T, but also Docusign, Rakuten and Woven by Toyota: faster and better at the tasks that meet your specific needs.
Today we’re taking a big step forward with MAI Licensed Weights: models under your control.
You take a frontier MAI model, customize it using your proprietary data if you want to. And then you run it securely in your own Azure environment.
You control who can access it. Your data and adaptations stay entirely yours. And we’ll work with you through Frontier Company to deliver the custom model and embed it in your own products and agents.
So that’s MAI, a family of world-class models with exceptional price-performance: the world’s best image editing model; the best transcription model; frontier cyber defense at 2% of the cost; and world-class everyday coding models at a price you can truly scale.
And crucially all of it with Your IQ. Your agents. Your weights. All under your control.
This is Frontier Intelligence you can trust, from the company you can trust.
·Models
MAI Image 2.7, our latest image editing model, launches with even stronger control for edits that are hardest to get right. It launches in preview at No. 3 on Arena Edit, making Microsoft AI the No. 2 lab, and No. 2 on Artificial Analysis’s image editing leaderboard.
Restyle or relight an entire scene, change text and symbols while keeping them integrated into the image, or restore and enhance existing assets. And make edits that require understanding how objects, lighting, and environments should work together.
Great image editing comes down to control over the details that matter. Like moving a product into a new setting. Shifting the lighting and mood. Reworking individual objects without losing the bigger picture.
MAI Image 2.7 improves on 2.6 across all 10 use cases and all 7 editing actions evaluated by Artificial Analysis. It reaches the category frontier in enhancement and restoration, reasoning-based edits, scene and style, and text or symbol editing. Its strongest lead is in scene and style, where it scores 24 Elo ahead of the next-best model.
For creators, that means more freedom to restyle a scene, fine-tune an asset, or bring a complex creative brief to life. It’s another step toward making powerful image editing more practical for everyday creative work.
Try MAI Image 2.7’s image editing capabilities today on Arena, Artificial Analysis and MAI Playground. We’re starting with editing, with text-to-image generation coming soon.
·Models
MAI Cyber 1.1 Flash takes vulnerability discovery a step forward, delivering comparable performance to MAI Cyber 1 Flash while costing 18% less per scan on an internal MDASH vulnerability-scanning evaluation suite.
With MAI Cyber 1 Flash, we showed what’s possible when a specialized security model, Microsoft’s security data, and the MDASH harness work together.
MAI Cyber 1.1 Flash builds on that foundation. It’s a more focused model that takes on more of the work itself, so the full MDASH system can surface useful findings at lower cost.
MAI Cyber 1.1 Flash is built to do more with less. On the same MDASH evaluation suite, each scan costs 18% less to complete on an internal product evaluation set.
The goal is bigger than making an individual model cheaper to run, making the entire vulnerability discovery system more efficient while preserving the performance defenders rely on.
Customers who try MAI Cyber 1 Flash in MDASH tend to stick with it. After running their first scan with the MAI Cyber 1 Flash profile, nearly 9 in 10 subsequent scans use the MAI profile rather than the OpenAI-only model profile.
To date, MAI Cyber now accounts for almost 50% of all MDASH scans with over thousands of scans from hundreds of customers. MAI Cyber 1.1 Flash brings those customers a more focused, efficient model within the workflow they already use.
MAI Cyber 1.1 Flash is available through MDASH to verified customers, with safeguards in place to support responsible use, including clear usage policies and ongoing monitoring.
·Health ·MAI Health Team
What if AI could help clinicians work through a complex medical diagnosis, step by step, and achieve higher accuracy, at lower cost, with fewer medical tests?
That future is now coming into view. On common presentations to a US emergency department, MAI-DxO – our AI diagnostic system – is 1.7 times more accurate than physicians when evaluated using cases from MIMIC-IV-ED.
And on medicine’s most complex cases, published in The New England Journal of Medicine, MAI-DxO is more than twice as accurate as physicians using textbooks and the internet – and nearly four times as accurate when they diagnose without those resources. It also manages to do this at half or even one third of the cost, getting to the right diagnosis with fewer tests and procedures.
Our work is published today in Science.
Read more about our vision for medical superintelligence also published this week in BMJ Digital Health and AI.
AI has the potential to transform health and healthcare, and progress is accelerating rapidly. The challenge now is to build and rigorously evaluate AI systems that translate advances in their clinical reasoning capabilities into meaningful impact.
Today’s paper, building on earlier work, introduces two foundations for that shift: the Sequential Diagnosis Benchmark (SDBench), which tests step-by-step diagnostic reasoning, and the Microsoft AI Diagnostic Orchestrator (MAI-DxO), our leading AI system on the benchmark.
Medical licensing exams such as the United States Medical Licensing Exams (USMLEs) are designed to assess physicians’ knowledge – not the realities of making a clinical diagnosis. In these tests, all information is presented upfront and a single answer is selected; in practice, clinicians must build the picture step by step, deciding what to ask, which tests to order and how each new finding changes the likely diagnosis. Such exams have become the common benchmarks for evaluating the performance of health AI.
That’s why we developed SDBench, which evaluates performance across two complementary sets of cases: 304 complex cases taken from The New England Journal of Medicine (NEJM) case proceedings and a set of more typical emergency-department presentations from MIMIC-IV-ED. Each becomes an interactive case in which AI models and/or physicians start with limited information and choose what to request next. The benchmark measures diagnostic accuracy, evidence requested and estimated test costs – assessing both the answer and the path taken.
We built MAI-DxO and tested it within SDBench. Rather than relying on one model for an immediate answer, it operates like a panel of virtual physicians: each proposing diagnoses, selecting useful questions or tests, and challenging the emerging view. MAI-DxO coordinates this exchange over several rounds of debate, updating its assessment as evidence arrives and weighing each test’s likely value against its cost.
What we found:
We are open-sourcing SDBench for select NEJM cases – including the benchmark, Gatekeeper, Judge and cost-estimation code – so researchers can reproduce the evaluation, test other models, and challenge or extend the findings.
Diagnosis is only one part of the care journey. Better care also requires keeping pace with medical knowledge, selecting the right treatment, understanding change over time, and supporting choices that reflect a person’s values and access to care. The opportunity is to unite these capabilities into a standard of care not widely available today. In Medical superintelligence: foundations and aspirations, published in BMJ Digital Health and AI, we explore what it would take for AI to support this broader vision – and ultimately exceed the capabilities of today’s strongest clinical teams and health systems.
Sequential diagnosis offers an early example: AI physicians collaborating, challenging assumptions and refining their clinical reasoning as evidence emerges. Our ambition is to build AI that connects knowledge, context and decisions across the care journey – not simply excels at one clinical task. Through our collaboration with Mayo Clinic, we aim to combine frontier AI, clinical expertise and longitudinal multimodal data to build systems for the complexity and diversity of real-world care.
Benchmarks matter, but the true test is performance in real clinical environments. Through a new partnership with Beth Israel Deaconess Medical Center in Boston, we will evaluate clinical reasoning capabilities across different hospital settings. In a prospective study, patients will interact with the system directly, with performance measured against physicians’ independent assessments. Working alongside clinical teams will show where the technology succeeds, where it falls short and how it can fit into busy workflows.
Rapid advances in medical AI are opening new possibilities for patients and clinicians. To turn this progress into practical impact, we are bringing together health teams from across Microsoft – including scientists from Microsoft Research and the teams behind products like Dragon Copilot and PowerScribe – into an integrated effort at Microsoft AI. Working together, we will accelerate the delivery of trusted AI systems that drive better clinical outcomes and care experiences.